
Generative AI development services.
From retrieval to fine-tuning to deployment, with evaluation at every step.
RAG development services
Production retrieval-augmented generation with hybrid search, reranking and knowledge-graph retrieval over your documents and data.
Learn more →RAG as a service
Your RAG pipeline delivered as a clean API that your products and teams can call, built and handed over to you.
LLM development and fine-tuning
LoRA adaptation, RLHF and model merging to adapt open models to your domain and tone.
Learn more →Private LLM deployment
Open-weight models served in your VPC or on-premise, so prompts and data never leave your environment.
Learn more →Evaluation and guardrails
Test sets, automated evaluation and safety guardrails so quality is measured, not assumed.
Generative AI products and copilots
Semantic search, copilots and AI features embedded into your SaaS or internal tools.
Learn more →How a RAG pipeline answers a question.
The same retrieval-augmented pattern sits behind most of the enterprise generative AI we build.
Your documents
PDFs, wikis, tickets, databases
Chunk and embed
Split, enrich and vectorise
Vector store
Hybrid search index
Retrieve and rerank
Find the best passages
LLM answer
Grounded, with citations
Engineers who build it, and hand it over.
A senior embedded team
Engineers and researchers who have shipped production AI before, working as an extension of your team.
100% IP and source code
You own the code, the models and the documentation. No lock-in, no black boxes.
Deploy where you need it
Your private cloud, VPC or on-premise infrastructure, so sensitive data stays in your control.
Open and model-agnostic
We pick the best open-weight or commercial model for the job, and design so you can swap it later.
How a generative AI build runs.
Define quality
We agree what good looks like and build an evaluation set from your real questions and documents.
Build the pipeline
Ingestion, chunking, retrieval, reranking and generation, tuned against the evaluation set.
Adapt the model
Fine-tune or prompt-engineer where it measurably helps, and choose the right model for cost and latency.
Deploy and monitor
Production deployment with guardrails, observability and a feedback loop, then handover.
Systems we have shipped.
Built a multi-modal AI platform that connects databases and document stores to generate websites, reports, and presentations — plus advanced agentic workflows for CRM and customer support.
Read case study →
A leading US-based materials testing lab improved customer retention by 35% and captured 42% more enterprise leads within six months by deploying a domain-trained AI chatbot.
Read case study →
An SME legal firm in India deployed Superteams.ai's AI-powered prototype for contract vetting, achieving 40% faster reviews, 35% better compliance, and 30% lower costs within six months.
Read case study →Engineering notes from our team.
A Guide to Building a RAG AI Assistant Using DeepSeek-R1
Learn to build an AI assistant using DeepSeek-R1’s reasoning model with an agentic RAG architecture for insightful responses over large knowledge bases.
Read article →
A Definitive Guide to Fine-Tuning LLMs Using Axolotl and Llama-Factory
Step by step guide to training or fine-tuning LLMs using no-code open source technologies
Read article →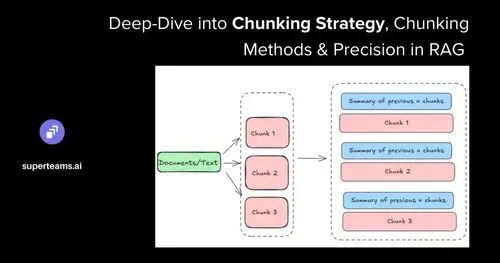
A Deep-Dive into Chunking Strategy, Chunking Methods, and Precision in RAG Applications
This article explores chunking strategies, implementation pipelines for evaluating them, advanced chunking methods, common implementation pitfalls, recent breakthroughs in the field
Read article →Frequently asked questions.
What is RAG (retrieval-augmented generation)?
RAG retrieves relevant passages from your own documents and data at query time and gives them to a language model, so answers are grounded in your content rather than only in what the model memorised. It reduces hallucinations and keeps answers current without retraining.
Should we use RAG or fine-tune an LLM?
RAG is usually the first choice for knowledge that changes or must be cited. Fine-tuning helps with style, format and domain behaviour. Many production systems combine both, and we measure which helps on your data.
What does RAG as a service mean here?
We build your RAG pipeline and expose it as an API your applications can call. You receive the code and infrastructure, so you are not tied to a vendor.
Can you build a private LLM for us?
Yes. We deploy open-weight models in your VPC or on-premise so prompts, documents and outputs stay in your environment.
How do you reduce hallucinations?
Through good retrieval, reranking, grounding and citations, evaluation against a test set, and guardrails. We measure answer quality rather than relying on demos.
Which models do you work with?
We are model-agnostic and work with open-weight families such as Llama, Mistral, Gemma and DeepSeek as well as commercial APIs, choosing for accuracy, cost, latency and data policy.
Ready to talk to an AI architect?
A free 30-minute strategy call. We will tell you honestly what is worth building and how.
Book my strategy call →